How Google Search Actually Works: Crawling, Indexing, Ranking Explained
Every search on Google returns results in a fraction of a second, which creates the illusion that Google is doing something simple and instantaneous. In reality, by the time you press enter, Google has already spent an enormous amount of computational effort — continuously, long before your specific query — discovering, parsing, and evaluating the trillions of documents that make up the indexed web. Understanding the three-stage pipeline behind this process — crawling, indexing, and ranking — is genuinely one of the most useful mental models a business owner can learn, because it explains almost every common SEO diagnostic question people ask.
Stage 1: Crawling — How Google Discovers Your Pages
Crawling is the discovery phase. Google uses automated programs, most commonly referred to as Googlebot, that traverse the web by following hyperlinks — much like a person clicking from page to page, except at a massive, continuous, distributed scale.
How Google finds new pages
Googlebot typically discovers new URLs through one of a few paths:
- Following hyperlinks from pages it has already crawled and indexed, whether internal links within a site or external links from other domains
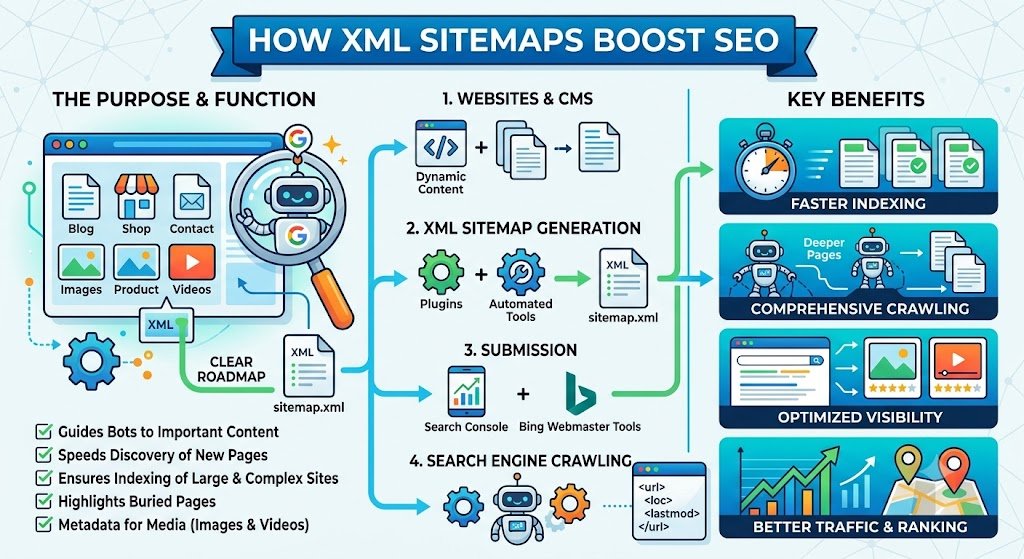
- XML sitemaps, structured files that explicitly enumerate a site’s URLs and are submitted through Google Search Console
- Direct submission, where a URL is manually queued for crawling via Search Console’s URL Inspection tool
What affects how well your site gets crawled
Robots.txt configuration. This file, governed by the Robots Exclusion Protocol, tells crawlers which parts of your site they’re permitted to access. A misconfigured robots.txt directive is a surprisingly common cause of URLs never being discovered at all.
Site structure and internal linking. URLs with no internal links pointing to them — often called orphan pages — are far harder for Googlebot to discover via its link-following traversal, even if they technically exist within the site.
Crawl budget. For very large websites, Google allocates a finite amount of crawling activity per domain, weighted by perceived site authority and server capacity. Wasting this budget on low-value URLs (thin filter pages, duplicate URLs with tracking parameters, faceted navigation permutations) can mean genuinely important pages get crawled less frequently.
Server response and page load performance. Slow Time to First Byte (TTFB) or unreliable server infrastructure can throttle how much of a site Googlebot is able to crawl within a given crawl session.
A critical point that’s often misunderstood: if a URL is never crawled, it cannot appear in search results, regardless of how good its content is. This is why crawl-layer issues are often the first thing to diagnose when a page mysteriously fails to rank.
Stage 2: Indexing — How Google Decides What to Keep
Once a URL has been crawled, Google’s indexing pipeline parses its content and renders the DOM to decide whether to admit it into the Google Index — an enormous, continuously updated database of documents eligible to appear in search results.
What happens during indexing
- Google parses the page’s text content, DOM structure, and any structured data (Schema.org/JSON-LD markup) to build a semantic understanding of exactly what the page represents
- It runs deduplication checks against the existing corpus to determine whether the content is unique, or a duplicate (or near-duplicate) of content that already exists elsewhere, triggering canonicalization logic if so
- It evaluates whether the content clears basic quality-classification thresholds
Why a page might be crawled but not indexed
This happens more often than most site owners realize, and it’s a distinct diagnostic category from a page simply not ranking well. Common causes include:
- Thin or low-value content that doesn’t provide sufficient substance to justify inclusion in the index
- Duplicate content, where near-identical URLs exist elsewhere (either on the same domain or scraped/syndicated from another source)
- Accidental noindex directives (via meta robots tag or X-Robots-Tag header) left in place from a staging environment or a misconfigured SEO plugin
- Domain-level quality issues, where Google’s classifiers have deprioritized indexing additional URLs from a site due to broader, aggregate quality concerns
Google’s 2026 core updates specifically increased classifier scrutiny at this stage, particularly around content that appeared to be produced at scale with minimal originality or human editorial oversight — informally described in the industry as “AI slop.” Sites publishing large volumes of this kind of content have seen a growing share of their URL inventory either excluded from the index entirely or ranked so far down as to be effectively unreachable.
Stage 3: Ranking — How Google Decides the Order
Ranking is the stage most people think of when they hear “SEO.” This is where, for a specific query, Google’s ranking algorithm evaluates all relevant indexed URLs and determines which to display, and in what SERP order.
The broad categories of ranking signals
Relevance. How closely the content’s semantic content matches the specific intent classification behind the search query — not just literal keyword overlap.
Quality and E-E-A-T. Experience, Expertise, Authoritativeness, and Trust — Google’s evaluative framework for assessing whether content was likely produced by someone genuinely knowledgeable, and whether the domain as a whole carries a track record of reliability.
Technical performance. Page speed, mobile usability, and Core Web Vitals field scores all factor into ranking, particularly as a tiebreaker when competing URLs are otherwise comparable in content quality.
Authority signals. Backlinks from other trustworthy, topically relevant domains, along with broader brand-entity reputation and recognition within Google’s Knowledge Graph.
User experience and engagement signals. How users interact with a result after clicking (post-click behavior) — though Google has been notably cautious about how heavily its ranking model weights these signals, given how easily they can be gamed.
Why ranking is dynamic, not static
Ranking isn’t computed once and cached indefinitely — it’s recalculated fresh for every individual query at serve time, and the underlying signal weights shift constantly as new content is published, existing content decays, competitors improve their pages, and Google’s own ranking models are retrained and updated. This is why a URL that ranked well a year ago can quietly slide down the SERP over time if it isn’t maintained, refreshed, or if competitors have simply produced something with greater information gain.
Where AI Overviews Fit Into This Pipeline
AI Overviews are not a separate system running independently of traditional search — they’re built on top of the same crawling, indexing, and ranking infrastructure via a retrieval-augmented generation (RAG) layer. When Google generates an AI-synthesized summary at the top of a SERP, it is pulling from content that has already been crawled, indexed, and judged sufficiently relevant and trustworthy through the standard ranking pipeline.
This has an important practical implication: there is no separate “AI SEO” trick that bypasses the fundamentals. Google’s own guidance on optimizing for generative search experiences, published in 2026, explicitly clarified that special formatting tricks or unusual technical workarounds are not required — the same fundamentals that drive strong traditional rankings (originality, information gain, demonstrated expertise, technical soundness) are what determine whether a URL gets selected for citation inside an AI Overview.
Diagnosing Common SEO Problems Using This Framework
Understanding this three-stage pipeline gives you a genuinely useful diagnostic decision tree. Here’s how to apply it to some of the most common questions business owners ask:
“Why isn’t my new page showing up in search at all?”
This is almost always a crawl-layer or indexing-layer issue, not a ranking issue. Check Google Search Console’s URL Inspection tool to see whether the URL has been crawled and indexed. If not, check for orphan-page status (no internal links pointing to it), a missing sitemap entry, or an accidental noindex directive.
“Why did my rankings suddenly drop?”
This is typically a ranking-stage issue, often tied to a broad core algorithm update that recalibrated how Google’s model evaluates quality or relevance signals for your content category. Reviewing whether your content still demonstrates clear expertise and information gain relative to current top-ranking competitors is the right starting diagnostic.
“Why does a competitor with worse content outrank me?”
This usually points to a gap in a signal external to the content itself — most commonly backlink profile authority and aggregate domain trust, or technical performance issues like Core Web Vitals scores on mobile.
“My page is indexed, but it never gets any traffic.”
This suggests the URL is being outranked for its target queries, which comes back to relevance and information gain relative to what currently occupies the top results — it may be time to genuinely rework the content at the information-architecture level rather than make small cosmetic edits.
Frequently Asked Questions
How long does it take for Google to crawl and index a new page?
This varies significantly based on how established your domain is and how easily Googlebot can discover the URL via the link graph. Well-established sites with strong internal linking might see new URLs indexed within days; newer or smaller domains can sometimes wait weeks.
Can I force Google to crawl my page faster?
Submitting the URL directly through Google Search Console’s URL Inspection tool can prompt an expedited crawl request, though it doesn’t guarantee immediate indexing or ranking.
Does having more pages help my site rank better overall?
Not inherently, and in some cases it can actively hurt. Google’s 2026 updates have specifically penalized domains with large volumes of thin, low-value URLs. A smaller number of comprehensive, well-maintained pages is a more reliable strategy than sheer inventory volume.
Final Thoughts
Crawling gets your content discovered. Indexing gets it parsed and made eligible. Ranking gets it seen — and increasingly, selected for citation by AI Overviews built on the very same underlying evaluation pipeline. Every meaningful SEO diagnostic question ultimately comes back to identifying which of these three pipeline stages is the actual bottleneck, and Google Search Console remains the single most useful free tool for finding out.
Want to make sure Google can find your pages in the first place? Our free Robots.txt & Sitemap Generator builds both files correctly in seconds.